Camera-controlled novel view synthesis
Trend on a fixed twelve-case subset of the evaluation: Mundo against video-generation and feed-forward baselines that render a ground-truth camera trajectory from posed context views.
Setup
- Cases. A fixed subset of the test set: the first two test scenes of ScanNet++ [7], DL3DV [8] and CA-1M [9] in identifier order, each with a near and a far trajectory, twelve cases in total. A trajectory is a real capture segment of thirteen keyframes; the far trajectory leaves the coverage of the context views.
- Inputs. Every method receives ground-truth camera poses and intrinsics and no depth. Methods that accept several images receive the same nine context views; FramePack receives the first one, Holo4D a 49-frame video that contains the nine views. FramePack and MiniMax H3 take no camera input and follow a text description of the trajectory.
- Metrics. Frames are cropped to a shared 4:3 canvas of 512×384 with identical rays for every method. PSNR, SSIM and LPIPS (VGG) on keyframes 1 to 12, over the full image and over the pixels that the context views see. Camera following: Pi3X estimates the cameras of the thirteen keyframes of each video, aligned to the ground truth with a similarity transform; ATE is divided by the extent of the trajectory.
- Training overlap. The DL3DV test scenes belong to DL3DV-10K, which is part of the training data of LagerNVS and Gen3C; whether these scenes were held out is not documented. Mundo was not trained on DL3DV or ScanNet++, and CA-1M test scenes are absent from its training data.
- Status. A method with fewer than twelve cases is still running; its means cover the cases listed and are not ranked.
Results
best in columnsecond best
| Method | Cases | Full image | Covisible pixels | Camera following | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| PSNR ↑ | SSIM ↑ | LPIPS ↓ | PSNR ↑ | SSIM ↑ | LPIPS ↓ | ATE ↓ | RPE-R ↓ | RotErr ↓ | ||
| Mundo 9 views | 12/12 | 15.181 | 0.528 | 0.452 | 15.390 | 0.540 | 0.442 | 0.028 | 1.316 | 3.268 |
| Stable Virtual Camera [1] 9 views | 8/12 | 14.409 | 0.583 | 0.506 | 14.672 | 0.602 | 0.487 | 0.030 | 1.185 | 2.928 |
| Gen3C [2] 9 views | 0/12 | – | – | – | – | – | – | – | – | – |
| Holo4D [3] 49-frame video | 0/12 | – | – | – | – | – | – | – | – | – |
| LagerNVS [4] 9 views | 12/12 | 19.126 | 0.686 | 0.389 | 19.712 | 0.704 | 0.370 | 0.029 | 1.233 | 2.749 |
| FramePack [5] 1 view + text | 12/12 | 9.989 | 0.368 | 0.673 | 10.046 | 0.369 | 0.668 | 0.231 | 10.415 | 47.273 |
| MiniMax H3 [6] 9 views + text | 8/12 | 10.433 | 0.336 | 0.640 | 10.368 | 0.343 | 0.641 | 0.126 | 12.773 | 60.559 |
| Ground-truth video estimator floor | 12/12 | – | – | – | – | – | – | 0.012 | 0.418 | 1.113 |
ScanNet++ [7]
| Method | Cases | Full image | Covisible pixels | Camera following | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| PSNR ↑ | SSIM ↑ | LPIPS ↓ | PSNR ↑ | SSIM ↑ | LPIPS ↓ | ATE ↓ | RPE-R ↓ | RotErr ↓ | ||
| Mundo 9 views | 4/4 | 14.429 | 0.583 | 0.468 | 14.822 | 0.612 | 0.457 | 0.023 | 1.351 | 3.151 |
| Stable Virtual Camera [1] 9 views | 4/4 | 13.127 | 0.559 | 0.508 | 13.271 | 0.581 | 0.498 | 0.038 | 1.107 | 2.752 |
| Gen3C [2] 9 views | 0/4 | – | – | – | – | – | – | – | – | – |
| Holo4D [3] 49-frame video | 0/4 | – | – | – | – | – | – | – | – | – |
| LagerNVS [4] 9 views | 4/4 | 17.361 | 0.689 | 0.442 | 17.932 | 0.720 | 0.423 | 0.031 | 0.982 | 2.276 |
| FramePack [5] 1 view + text | 4/4 | 8.215 | 0.392 | 0.690 | 8.284 | 0.403 | 0.687 | 0.212 | 12.526 | 51.413 |
| MiniMax H3 [6] 9 views + text | 4/4 | 9.206 | 0.444 | 0.667 | 9.157 | 0.463 | 0.667 | 0.147 | 18.518 | 88.795 |
| Ground-truth video estimator floor | 4/4 | – | – | – | – | – | – | 0.023 | 0.638 | 1.535 |
DL3DV [8]
| Method | Cases | Full image | Covisible pixels | Camera following | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| PSNR ↑ | SSIM ↑ | LPIPS ↓ | PSNR ↑ | SSIM ↑ | LPIPS ↓ | ATE ↓ | RPE-R ↓ | RotErr ↓ | ||
| Mundo 9 views | 4/4 | 15.865 | 0.394 | 0.377 | 15.894 | 0.393 | 0.372 | 0.011 | 0.548 | 1.585 |
| Stable Virtual Camera [1] 9 views | 0/4 | – | – | – | – | – | – | – | – | – |
| Gen3C [2] 9 views | 0/4 | – | – | – | – | – | – | – | – | – |
| Holo4D [3] 49-frame video | 0/4 | – | – | – | – | – | – | – | – | – |
| LagerNVS [4] 9 views | 4/4 | 21.139 | 0.658 | 0.274 | 21.402 | 0.667 | 0.262 | 0.005 | 0.161 | 0.578 |
| FramePack [5] 1 view + text | 4/4 | 11.397 | 0.236 | 0.626 | 11.425 | 0.234 | 0.626 | 0.256 | 5.565 | 32.054 |
| MiniMax H3 [6] 9 views + text | 4/4 | 11.661 | 0.229 | 0.612 | 11.580 | 0.224 | 0.615 | 0.105 | 7.029 | 32.323 |
| Ground-truth video estimator floor | 4/4 | – | – | – | – | – | – | 0.003 | 0.122 | 0.443 |
CA-1M [9]
| Method | Cases | Full image | Covisible pixels | Camera following | ||||||
|---|---|---|---|---|---|---|---|---|---|---|
| PSNR ↑ | SSIM ↑ | LPIPS ↓ | PSNR ↑ | SSIM ↑ | LPIPS ↓ | ATE ↓ | RPE-R ↓ | RotErr ↓ | ||
| Mundo 9 views | 4/4 | 15.249 | 0.606 | 0.511 | 15.454 | 0.615 | 0.498 | 0.049 | 2.049 | 5.069 |
| Stable Virtual Camera [1] 9 views | 4/4 | 15.691 | 0.607 | 0.504 | 16.073 | 0.623 | 0.476 | 0.022 | 1.264 | 3.103 |
| Gen3C [2] 9 views | 0/4 | – | – | – | – | – | – | – | – | – |
| Holo4D [3] 49-frame video | 0/4 | – | – | – | – | – | – | – | – | – |
| LagerNVS [4] 9 views | 4/4 | 18.879 | 0.712 | 0.452 | 19.802 | 0.725 | 0.424 | 0.052 | 2.557 | 5.391 |
| FramePack [5] 1 view + text | 4/4 | 10.355 | 0.475 | 0.703 | 10.428 | 0.469 | 0.689 | 0.226 | 13.154 | 58.351 |
| MiniMax H3 [6] 9 views + text | 0/4 | – | – | – | – | – | – | – | – | – |
| Ground-truth video estimator floor | 4/4 | – | – | – | – | – | – | 0.011 | 0.495 | 1.363 |
Cases
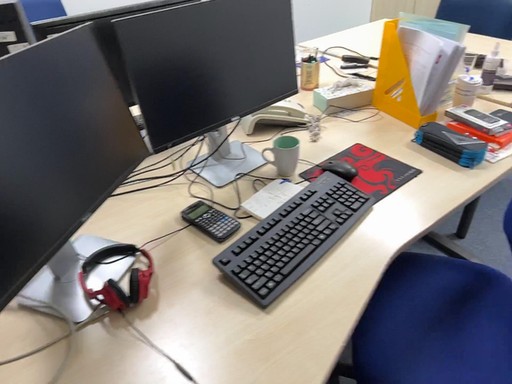
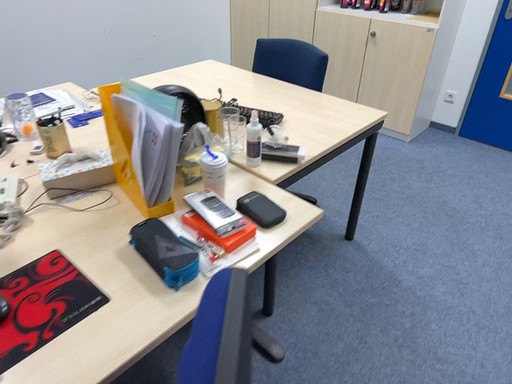
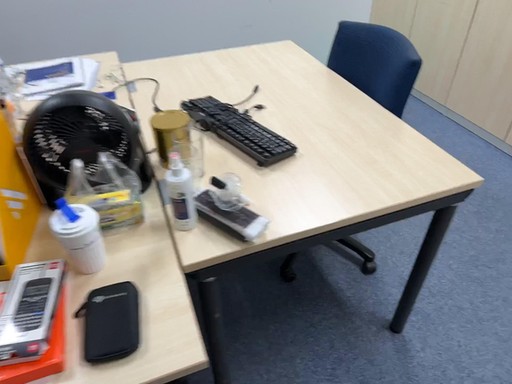
ScanNet++ · 0529d56cce · near trajectorycovisibility 0.87, 2.8 m, 82°
Context views (the first is the trajectory start)
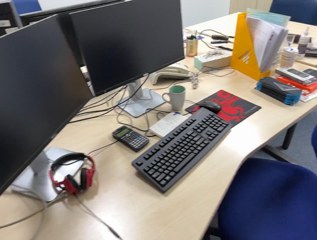
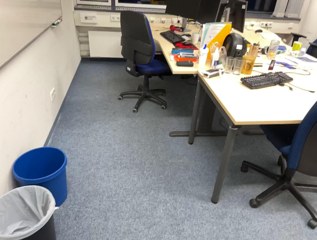
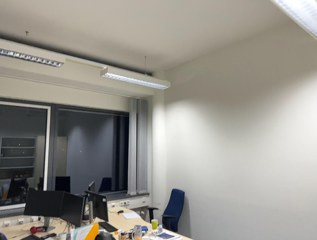
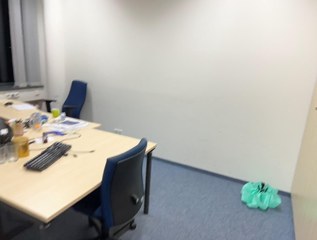
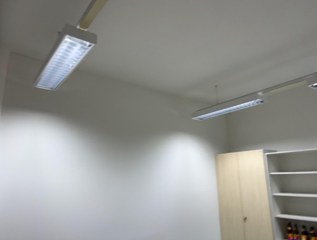
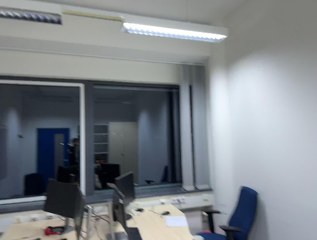
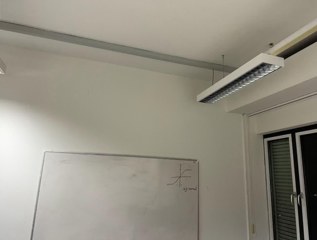
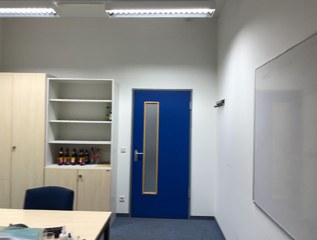
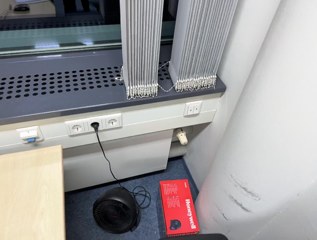
Ground-truth keyframes 0, 3, 6, 9, 12
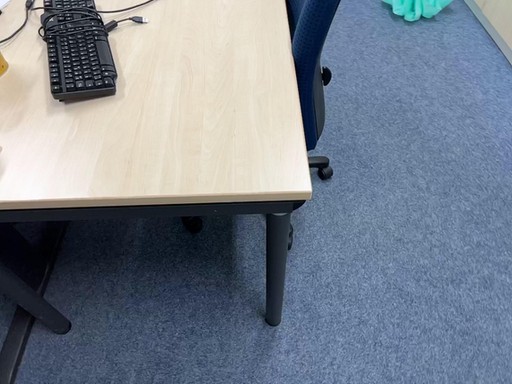
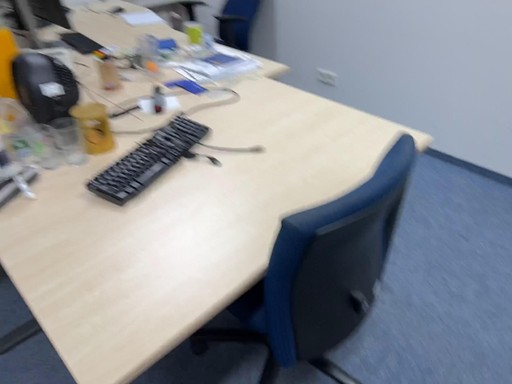
ScanNet++ · 0529d56cce · far trajectorycovisibility 0.55, 1.8 m, 68°
Context views (the first is the trajectory start)
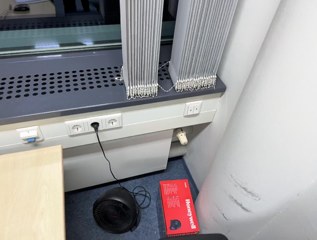
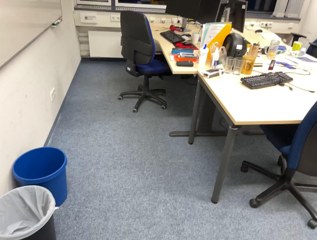
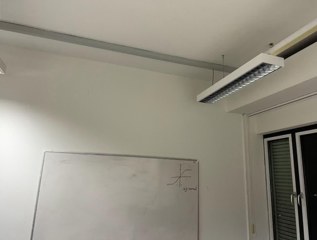
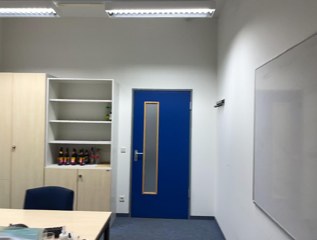
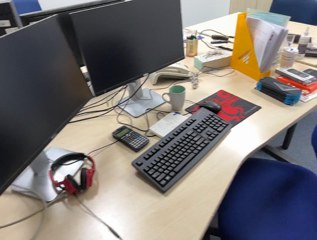
Ground-truth keyframes 0, 3, 6, 9, 12
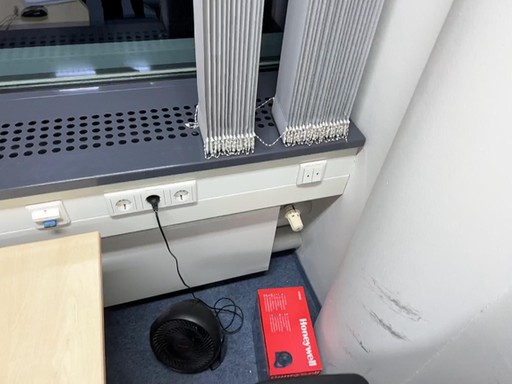
ScanNet++ · 1ada7a0617 · near trajectorycovisibility 0.86, 0.8 m, 170°
Context views (the first is the trajectory start)
Ground-truth keyframes 0, 3, 6, 9, 12
ScanNet++ · 1ada7a0617 · far trajectorycovisibility 0.72, 1.0 m, 117°
Context views (the first is the trajectory start)
Ground-truth keyframes 0, 3, 6, 9, 12
CA-1M · 42897521 · near trajectorycovisibility 0.89, 1.1 m, 95°
Context views (the first is the trajectory start)
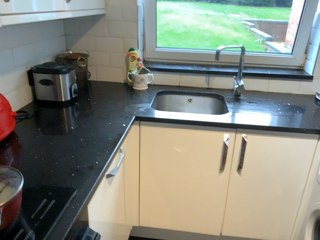
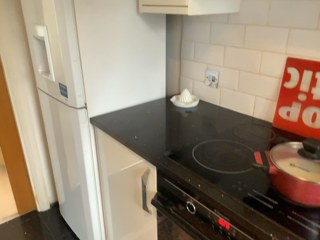
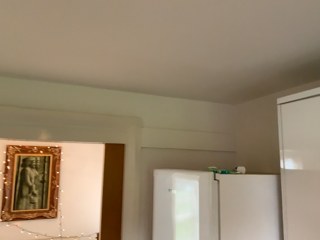
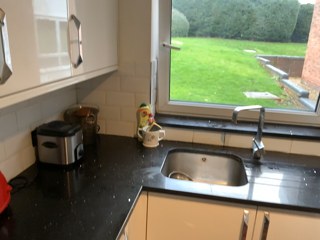
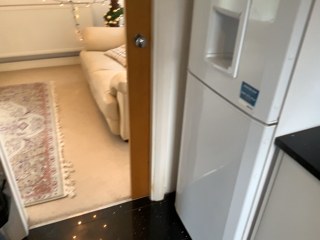
Ground-truth keyframes 0, 3, 6, 9, 12
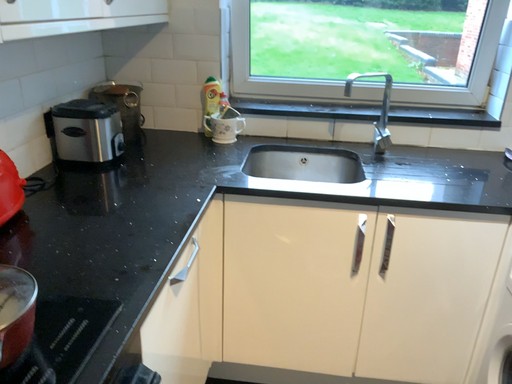
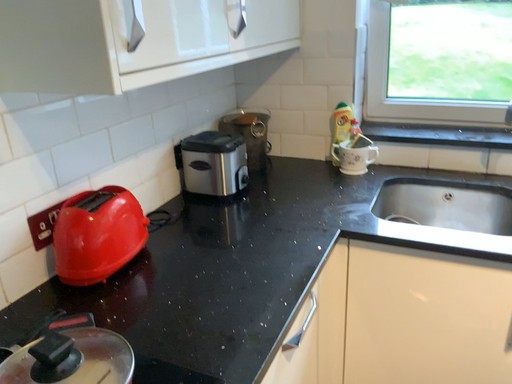
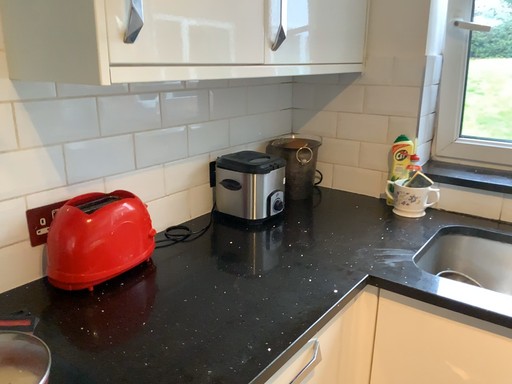
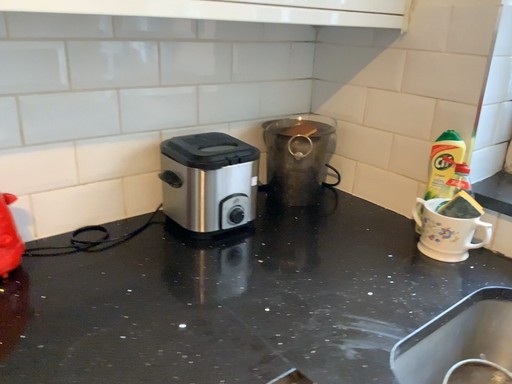
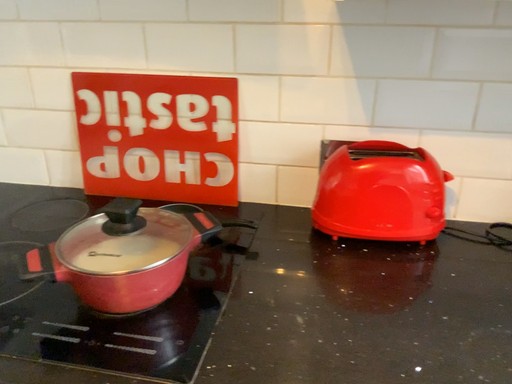
CA-1M · 42897521 · far trajectorycovisibility 0.66, 1.3 m, 179°
Context views (the first is the trajectory start)
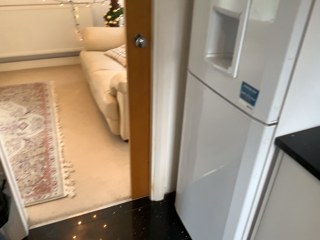
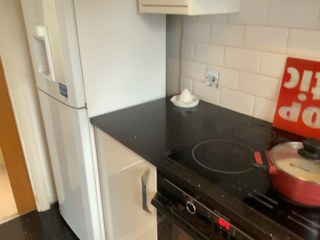
Ground-truth keyframes 0, 3, 6, 9, 12
CA-1M · 42897545 · near trajectorycovisibility 0.92, 2.2 m, 57°
Context views (the first is the trajectory start)
Ground-truth keyframes 0, 3, 6, 9, 12
CA-1M · 42897545 · far trajectorycovisibility 0.49, 2.1 m, 106°
Context views (the first is the trajectory start)
Ground-truth keyframes 0, 3, 6, 9, 12
DL3DV · 165f5af8bf · near trajectorycovisibility 0.96, 5.2 m, 75°
Context views (the first is the trajectory start)
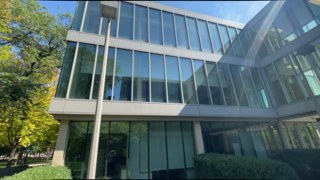
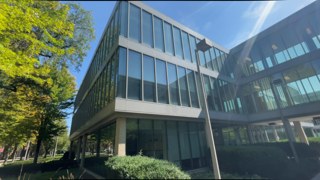
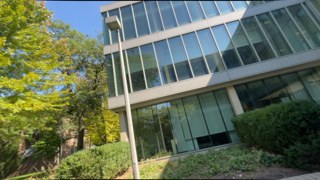
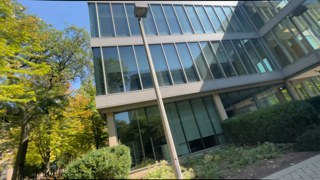
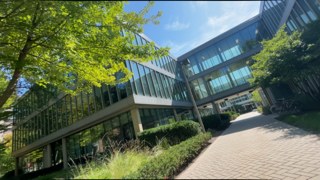
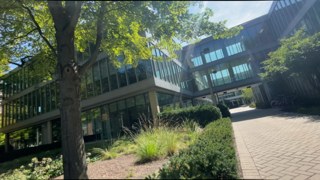
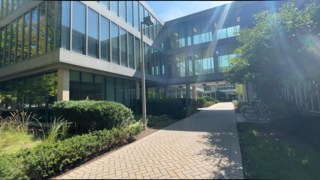
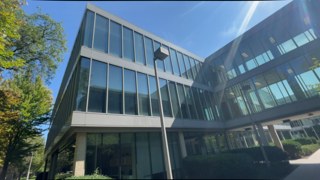
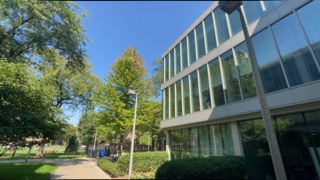
Ground-truth keyframes 0, 3, 6, 9, 12
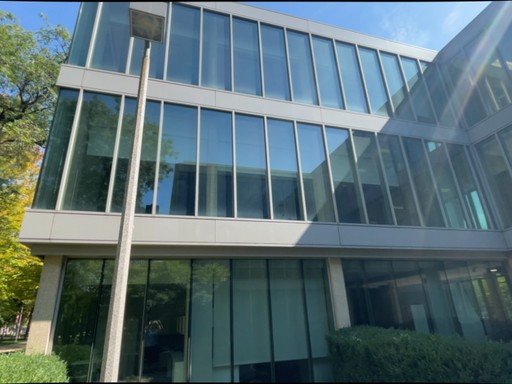
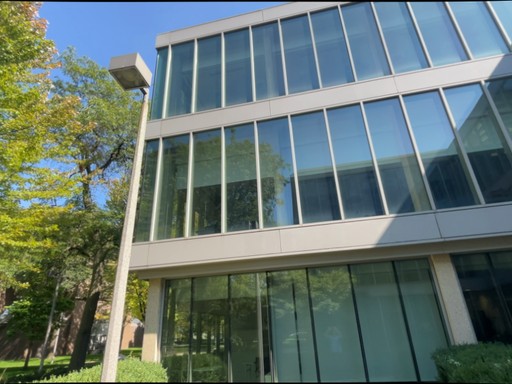
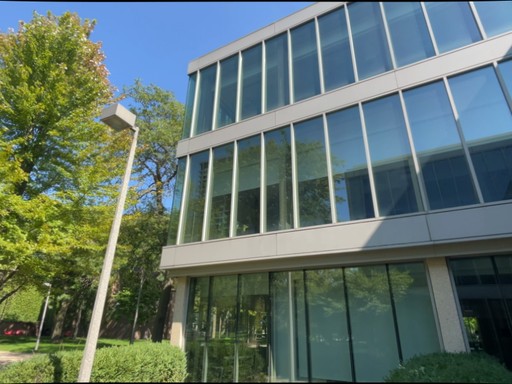
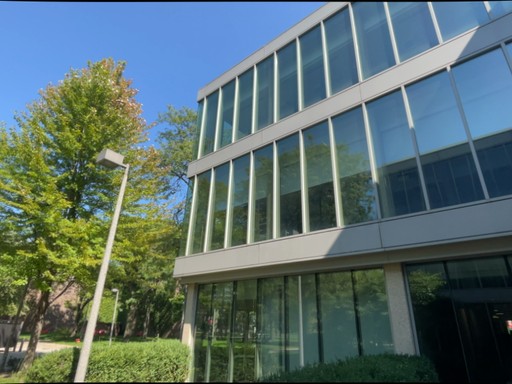
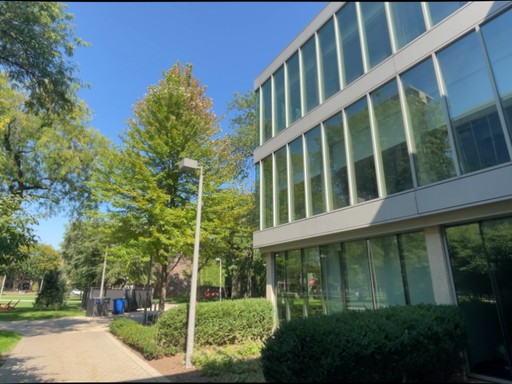
DL3DV · 165f5af8bf · far trajectorycovisibility 0.88, 2.6 m, 31°
Context views (the first is the trajectory start)
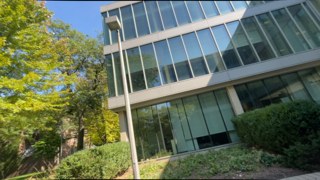
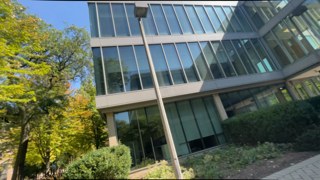
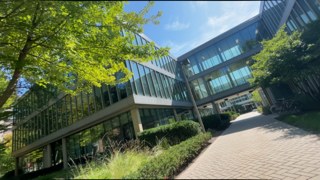
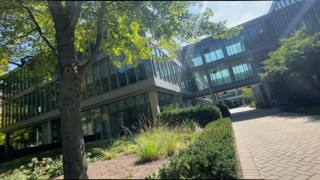
Ground-truth keyframes 0, 3, 6, 9, 12
DL3DV · 341b4ff3df · near trajectorycovisibility 1.00, 4.5 m, 63°
Context views (the first is the trajectory start)
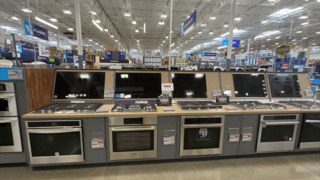
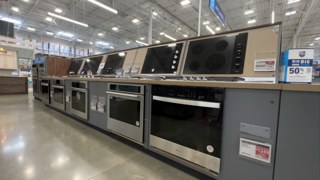
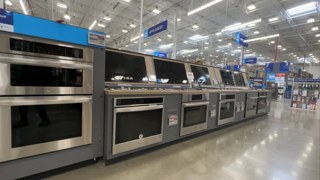
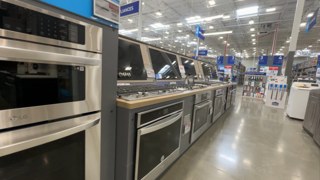
Ground-truth keyframes 0, 3, 6, 9, 12
DL3DV · 341b4ff3df · far trajectorycovisibility 0.80, 3.7 m, 35°
Context views (the first is the trajectory start)
Ground-truth keyframes 0, 3, 6, 9, 12
References
- Zhou et al. Stable Virtual Camera: generative view synthesis with diffusion models. arXiv 2503.14489.
- Ren et al. GEN3C: 3D-informed world-consistent video generation with precise camera control. CVPR 2025.
- Lan et al. Holo4D: holistic 4D reconstruction as geometric control for video diffusion. arXiv 2610.25276.
- Szymanowicz et al. LagerNVS: latent geometry for fully neural real-time novel view synthesis. CVPR 2026.
- Zhang and Agrawala. Packing input frame context in next-frame prediction models for video generation (FramePack). arXiv 2504.12626.
- MiniMax. MiniMax-H3 (Ref2VA), open-weight video generation model.
- Yeshwanth et al. ScanNet++: a high-fidelity dataset of 3D indoor scenes. ICCV 2023.
- Ling et al. DL3DV-10K: a large-scale scene dataset for deep learning-based 3D vision. CVPR 2024.
- Lazarow et al. Cubify Anything: scaling indoor 3D object detection (CA-1M). CVPR 2025.